What’s New in EdgeTier? Q3 Product Update
From self-serve Sonar anomaly models to a smarter, shareable Ask Spotlight and a fully transparent QA dispute process, here's everything
AutoQA lets you review every customer conversation instead of a small sample. Coverage is only part of the story, though. A QA veteran with two decades of experience explains why coverage without ongoing calibration just gives you a bigger, unverified spreadsheet, and what a team actually needs before trusting an AI score enough to act…
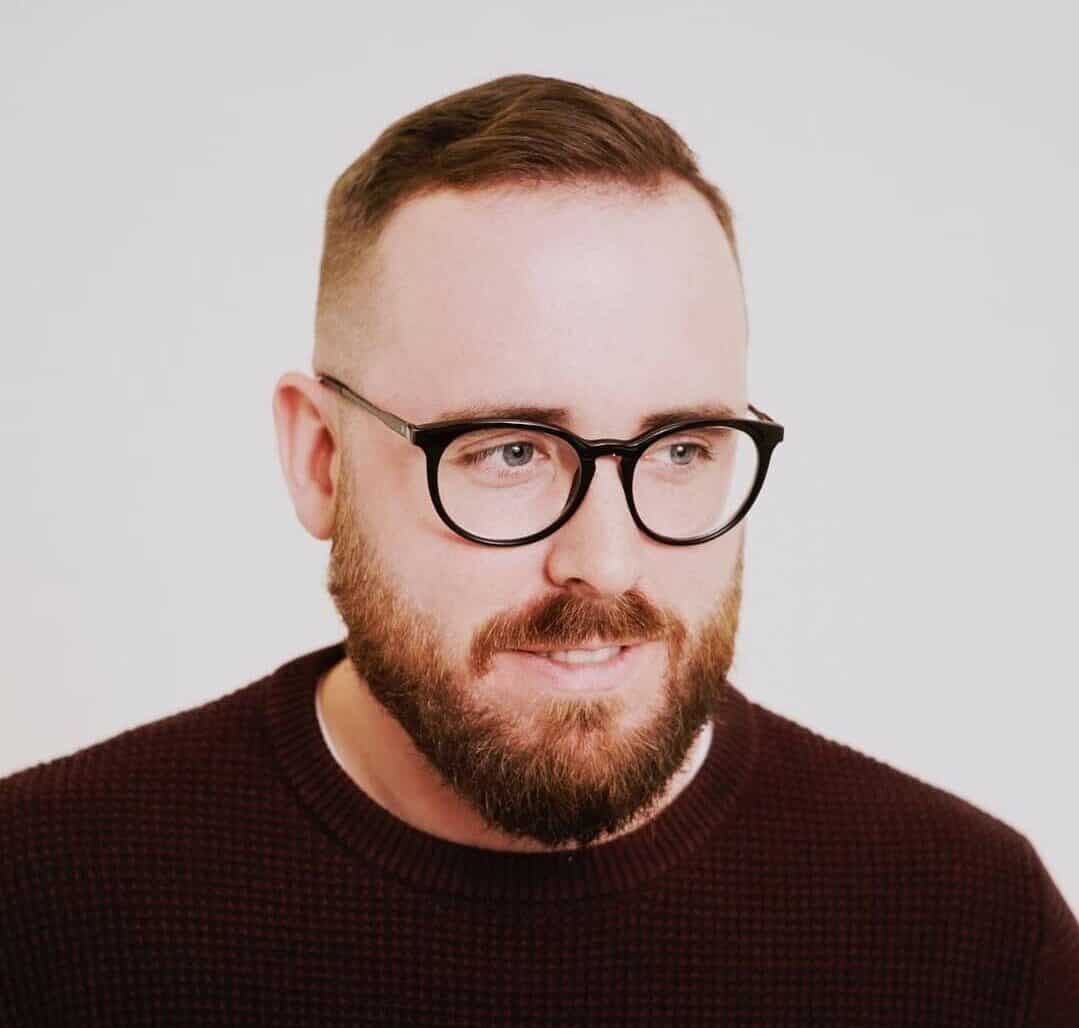
Every QA team runs on the same compromise: you can’t listen to everything, so you listen to enough. That’s been true for so long that most people don’t even clock it as a compromise anymore. It’s just how QA works. You pick a sample, you build a scorecard, and you hope the couple hundred conversations you reviewed say something true about the thousands you didn’t.
AutoQA breaks that assumption.
We sat down on a webinar with Pierot Salazar working through what actually happens once you can review every conversation instead of a sample of one. Salazar has run Quality Assurance for two decades across customer service, project management, and product, and he’s implemented this process every way there is to run it, from fully manual to fully automated.
Watch the webinar: HERE
Bart opened with an analogy that’s hard to argue with once you hear it:
“I don’t think any football coach would ever watch one minute of a match and then think that they have enough information to coach a team or to give advice to players on a team. But that is kind of what’s happening in a lot of QA processes.”
That’s the tradeoff most QA teams live with. Thousands of calls or chats come in every month, a handful of people can actually review them, and a scorecard needs filling out. Salazar put a real number on what that compromise looks like: out of 5,000 conversations, a standard sample at a 95% confidence level lands you around 400 reviewed. Statistically sound, and still a sample. As he put it:
“A sample can give you a picture without necessarily giving you the whole story.”
One unusually bad call ends up representing an agent’s whole month. A process issue showing up 500 times can sit entirely outside that sample of 400, invisible until it’s already cost you customers.
The obvious pitch for AutoQA is coverage: instead of sampling, everything gets scored. That part isn’t the interesting part. What’s more interesting is what happens to the quality assurance job once reviewing stops eating all of someone’s time. Salazar described his own role shifting away from pulling data and chasing down trends by hand, and toward actually interpreting what the numbers mean and deciding what to do about it. Less time building the report, more time acting on it.
Bart asked how much a team should trust an automated score, and Salazar didn’t soften it:
“I don’t think a QA team or a QA manager should simply take an AI score at face value.”
Before anyone acts on a score, his bar is that the evaluation criteria need to be clearly defined, and the QA team needs proof the AI is actually interpreting them correctly. That means running AI scores against human ones on an ongoing basis, not once during setup and never again. He compared it to building a machine: you build it, calibrate it, find an error, calibrate it again, and the calibrating never really stops.
When Bart pushed him on what separates a good AutoQA rollout from a company that just automated its old scorecard, Salazar’s answer came down to five things:
A dashboard full of scores nobody acts on isn’t quality assurance. It’s just a bigger spreadsheet.
This is the part most people actually want to know: does AutoQA come for QA jobs? Salazar’s answer was direct, and the shape of the new job is more interesting than the reassurance itself. Instead of manually scoring conversations, the team now spends its time checking what the AI got wrong, especially on low-scoring or high-frustration conversations, and feeding those corrections back in. He had a tight way of putting it:
“It’s a QA of the AutoQA.”
He also mentioned that agents were more skeptical than management going in, which tracks. Nobody loves hearing “an AI is going to score your calls now.” The skepticism faded once people understood they weren’t about to become full-time AI babysitters either. QA analysts got to stop doing the same repetitive evaluation over and over and started spending more time on coaching and root-cause work instead, which is the part of the job most of them actually wanted to be doing.
Salazar doesn’t think the next stage of AutoQA is more automation on top of the scorecard. It’s connecting QA to the rest of the operation, and getting past “this happened” into “here’s why it happened.” Knowing that an issue occurred 500 times isn’t the hard part anymore. Figuring out the root cause and which team needs to fix it, that’s the harder problem, and it’s the one he expects the category to spend the next few years working on: better explainability, tighter feedback loops with the teams who can actually fix a broken process, and less time spent proving a problem exists.
Which gets back to the thing worth sitting with from this whole conversation. AI can review a hundred thousand conversations before lunch. That was never really the question. The question Bart asked toward the start of the call is still the one that matters most:
“Just because technology can do something doesn’t necessarily mean that it should.”
Coverage is easy to sell. Trust is the actual product.
EdgeTier Coach transforms contact centre quality assurance. Learn more HERE
No, according to Salazar. AI can score conversations at scale, but someone still needs to define what “good” looks like, validate the AI’s results, and dig into the conversations it gets wrong. The job shifts from reviewing calls to reviewing the AI.
It removes the manual sampling and scoring, not the oversight. In Salazar’s setup, the team filters AI-scored conversations, for example anything under an 80% score or flagged for frustration, and reviews that subset instead of every conversation.
Through ongoing calibration: comparing AI scores against human ones, digging into the mismatches, and adjusting criteria as the AI runs into new context. This isn’t a one-time setup step. It keeps going for as long as the system is in use.
In Salazar’s example, sampling 5,000 conversations at a 95% confidence level gets you roughly 400 reviewed conversations. AutoQA scores all 5,000, which removes the risk that a recurring issue simply never shows up in the sample.
From self-serve Sonar anomaly models to a smarter, shareable Ask Spotlight and a fully transparent QA dispute process, here's everything
EdgeTier turns your customer conversations into a single connected system: it catches anomalies before they escalate, scores every agent interaction
Most Ask Spotlight conversations run to about two messages. The longest one we found ran to forty-eight. Both can be

Debbie Duggan
Contract Manager for Customer Solutions
"We thought at the time that we were putting the customer at the fore. We thought we were doing things right. But in hindsight, we really weren’t because we had no real-time insights whatsoever into customer issues."


Nick Brazitis
Global Customer Care Manager
"The anomaly feature is a game changer for us. It’s highly accurate and has helped us identify customer issues, agent errors, and even fraud that would have taken us longer to catch."

Quentin Bottner
Head of Continuous Improvement
"We’re a big business, so getting the right people to agree and fix something hasn’t always been easy. Now we’ve got one version of the truth—it’s much easier to align and act"
Let us help your company go from reactive to proactive customer support.
Unlock AI Insights